Context
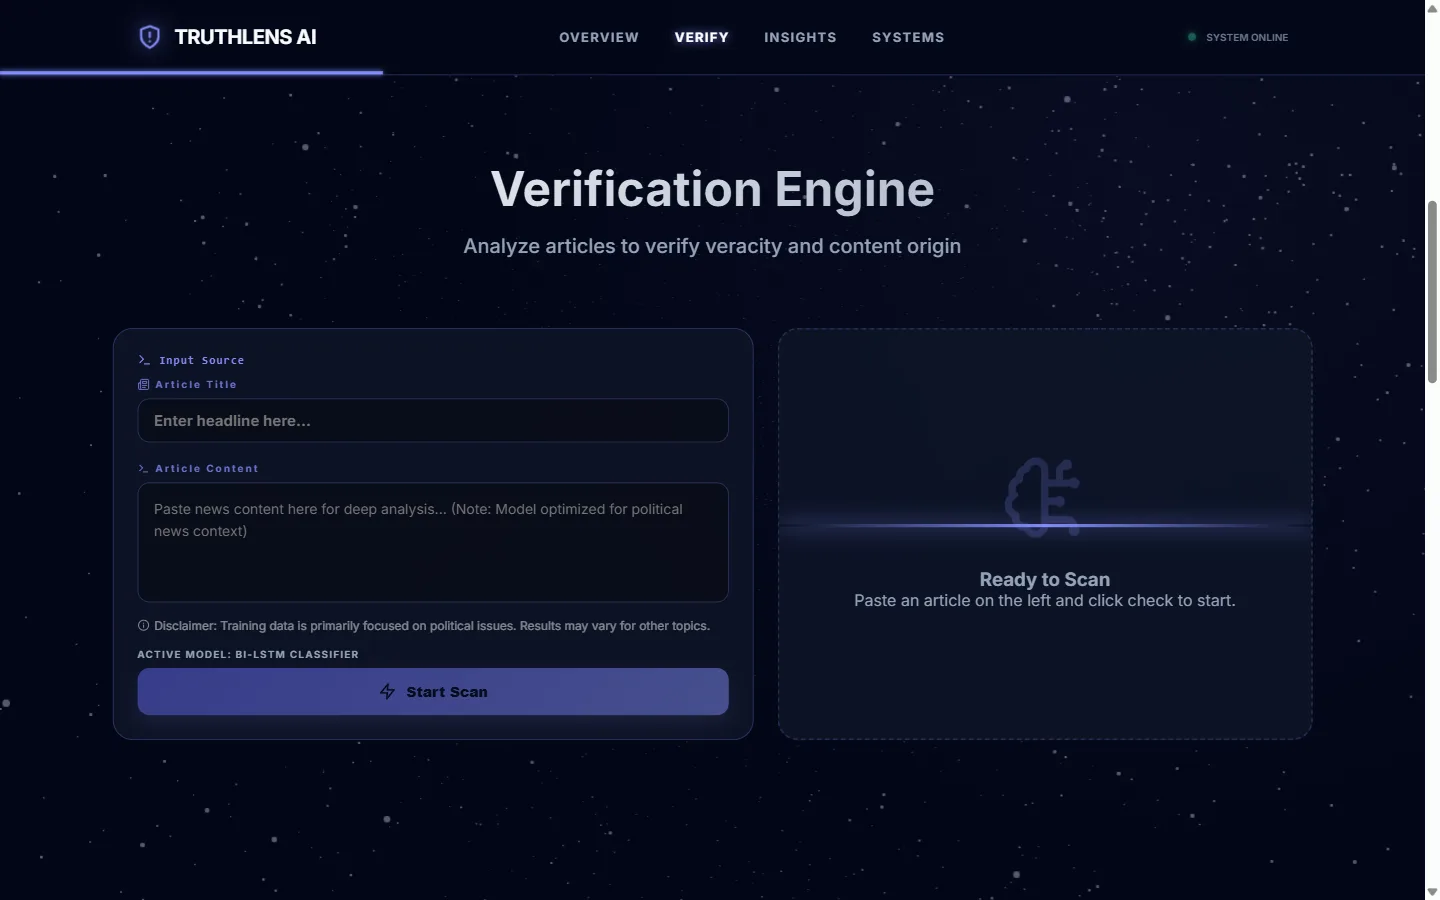
An online article raises two different questions: does it contain reliable information, and was it written by a person or generated by AI? TruthLens explores both through a shared learning framework, using the article title and content as inputs.
The project combined an academic comparison of four NLP architectures with a web application for trying the resulting classifier.
My contribution
I supported the dataset-generation workflow, data preparation, model-training experiments, and evaluation. I also co-wrote the paper’s methodology, implementation, and evaluation sections.
Our primary developer led the end-to-end technical pipeline and fullstack application. My contribution focused on the research and model-development work within that team.
Approach
We combined WELFake news data with synthetic articles generated using several model families and prompting strategies. The final dataset contained 26,000 articles, divided into 70% training, 15% validation, and 15% testing.
Each architecture used a shared encoder with two classification heads: Fake/Real and AI/Human. We compared a Bi-LSTM baseline with DistilRoBERTa, RoBERTa-base, and DeBERTa-v3-base under the same evaluation framework.
Training larger models within limited GPU memory required mixed precision, gradient accumulation, and architecture-specific batch sizes.
Results
| Architecture | Joint F1 |
|---|---|
| Bi-LSTM | 0.9614 |
| DistilRoBERTa | 0.9852 |
| RoBERTa-base | 0.9914 |
| DeBERTa-v3-base | 0.9874 |
RoBERTa-base achieved the strongest clean-test result, including Fake/Real F1 of 0.9882 and AI/Human F1 of 0.9947. Bi-LSTM was selected for deployment because of its smaller memory footprint. The application therefore represents a separate deployment decision from the highest-scoring experiment.
Limitations and lessons
The dataset’s language, subject matter, and class imbalance limit what these scores establish. We used one fixed seed, and broader testing against unseen generators and adversarial input remains further work.
This project made the distinction between evaluation and deployment concrete: a strong benchmark result is one part of choosing a model that can run within practical constraints.
MY CONTRIBUTION AT A GLANCE
- Assisted with synthetic-news generation and preparation of 6,000 AI-generated articles.
- Contributed to preprocessing, training, and evaluation across four NLP architectures.
- Co-wrote the methodology, implementation, and evaluation sections of the research paper.